
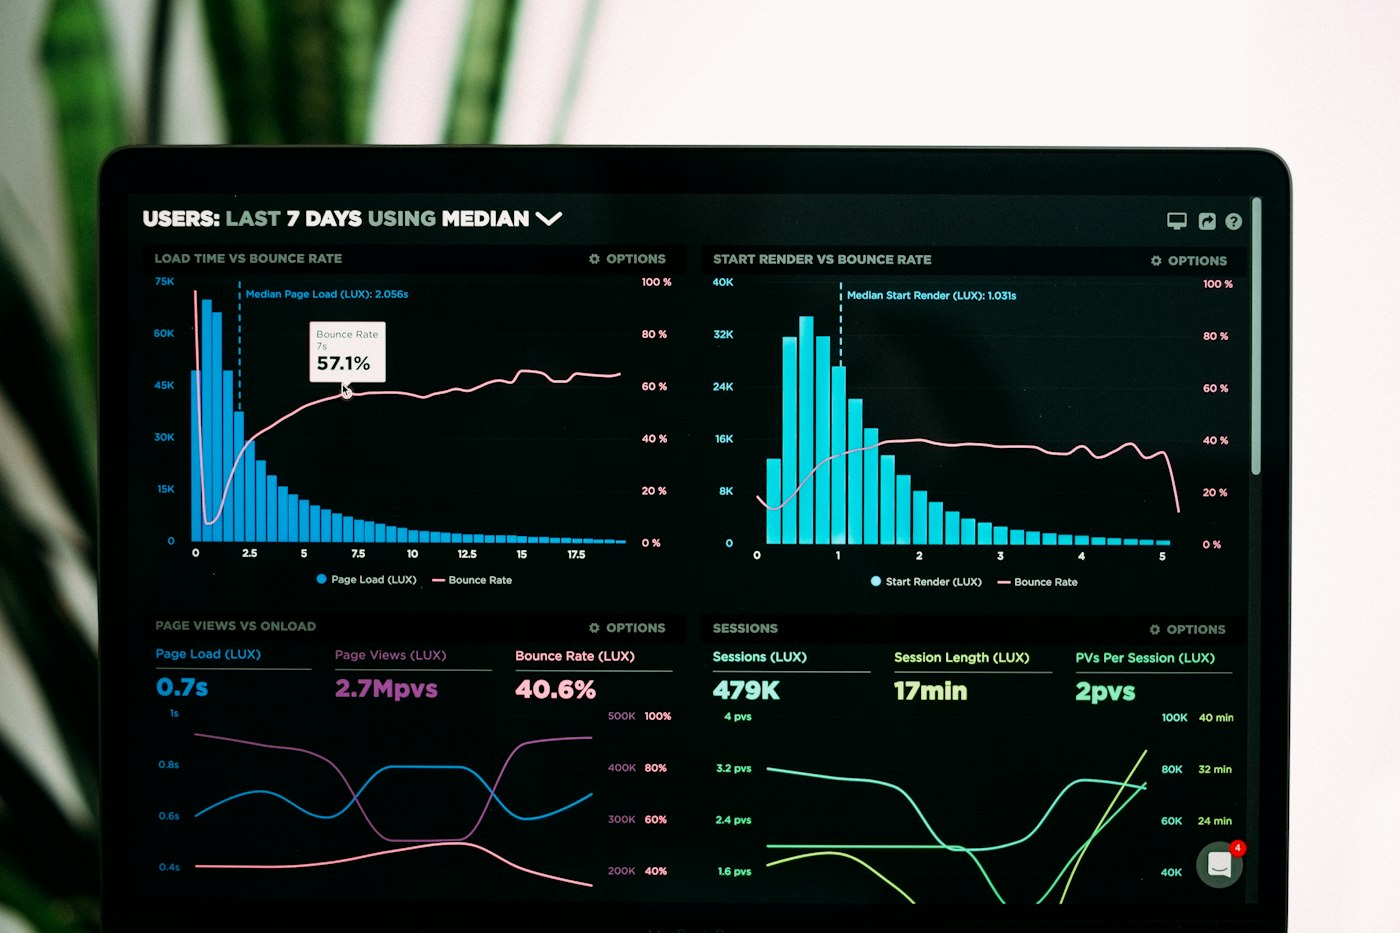
Production Machine Learning Pipelines: Ingestion, Feature Leakage, and Continuous Retraining
Notebook workflows give a false sense of security: load a static CSV, execute a Scikit-Learn transformer, fit an estimator, and evaluate an validation metric. In live production runtimes, model weights represent a fraction of system complexity. The true engineering challenge lies in building deterministic data harnesses capable of validating schemas, avoiding feature leakage, and synchronizing inference state across distributed clusters.
This technical breakdown traces the end-to-end architecture of production machine learning pipelines, analyzes the silent edge cases that corrupt production inference, and details the infrastructure patterns required for deterministic retraining.
The Architectural Gap: Dynamic Data vs. Static Weights
Software engineering patterns rely on code determinism: identical code inputs yield predictable system behavior. Machine learning introduces a dual dependency where behavior is governed by compiled code and dynamic data distributions. If upstream batch extracts mutate column types, introduce null tokens, or alter categorical cardinality, model inference degrades without throwing traditional syntax exceptions.
Production pipelines prevent this by implementing strict data contracts at ingestion boundaries, decoupling data transformation logic from serving infrastructure, and maintaining immutable artifact lineage across every training run.
Schema validation layers and feature stores form the baseline defense against training-serving skew.
Anatomy of an Enterprise ML Pipeline
Extracting raw partitions from object storage (S3/GCS) or warehouse tables via connector pools. Before memory allocation, data passes schema verification layers (such as Great Expectations or Pydantic) to halt execution on null spikes or type mismatches.
Transforming raw transactional records into dense mathematical tensors. Numerical scaling, categorical target encoding, and embedding lookups must execute using pre-computed statistics persisted as isolated transformation artifacts to prevent serving drift.
Isolating training, validation, and holdout datasets. For time-series or event-driven models, random k-fold splits introduce catastrophic lookahead bias. Data must partition across temporal cutoff boundaries to replicate real-world forward testing.
Orchestrating GPU/CPU workers across containerized runners. Training runs log hyperparameter iterations, convergence loss curves, and system telemetry back to central metadata backends like MLflow.
Evaluating candidates against production baselines using slice-based metrics. A candidate model cannot replace an active model based on global accuracy alone; it must match or exceed thresholds across critical sub-demographics and worst-case distribution tails.
Serializing verified weights alongside their exact inference graph and dependency manifests into an immutable Model Registry, triggering automated container packaging for canary deployments.
Silent Pipeline Failures and How to Mitigate Them
- Target and Temporal Leakage: Including signals in training features that would be unavailable during live inference (e.g., using post-conversion transaction timestamps). Mitigation requires strict time-travel query semantics within feature stores.
- Training-Serving Skew: Discrepancies between SQL batch pipelines used for training feature extraction and low-latency Python/Go logic running inside production inference microservices. Using centralized Feature Stores (such as Feast) guarantees parity between online and offline feature generation.
- Covariate Shift vs. Concept Drift: Covariate shift occurs when input distributions shift ($P(X)$ changes while $P(Y|X)$ remains constant); concept drift occurs when underlying statistical relationships change ($P(Y|X)$ changes). Detecting these variations requires continuous Kolmogorov-Smirnov and Population Stability Index (PSI) testing against incoming inference payloads.
Orchestration Architecture: Moving Beyond Cron
Triggering sequential training scripts with simple scheduling scripts fails in distributed systems due to unhandled node evictions and missing dependency graphs. Modern MLOps architectures orchestrate pipelines as Directed Acyclic Graphs (DAGs) using platforms like Apache Airflow, Prefect, or Kubeflow Pipelines.
These orchestrators isolate each step into containerized execution tasks, handle backfill logic automatically, and enforce deterministic artifact handoffs via persistent volume mounts and object stores.
Decouple the pipeline into distinct compute profiles. Ingestion and feature extraction demand memory-optimized instances with high disk throughput, while training stages require burst GPU clusters. Packaging each stage into self-contained Docker containers managed by a DAG orchestrator prevents resource bottlenecks and optimizes cloud infrastructure costs.
Building reliable machine learning systems requires shifting focus from algorithmic hyperparameter tuning to defensive data engineering. Enforcing schema contracts, preventing temporal leakage, and maintaining unified feature stores ensures models deliver consistent business value long after initial deployment.
Key Takeaways
- Schema contracts at ingestion boundaries prevent malformed payloads from silently corrupting model weights.
- Time-based temporal partitioning is critical to eliminate future-data lookahead bias in real-world models.
- Feature stores eliminate training-serving skew by sharing transform logic between offline training and online APIs.
- Statistical drift monitoring via PSI and Kolmogorov-Smirnov tests triggers automated retraining before performance collapses.
great
ReplyDelete